
GraphRAG-Benchmark
GraphRAG-Benchmark evaluates graph-based RAG holistically: graph construction, retrieval/path selection, and reasoning consistency—not just answers. On the Medical domain, we measure how the WGS RAG layer improves end-to-end quality and evidence grounding.
+15 points on average: WGS turns strong backbones into stronger systems
Avg RAG Performance Model / Avg Performance
Evidence recall Model / task recall
WGS RAG shows the highest average evidence recall in this set, across fact retrieval, complex reasoning, contextual summarize, and creative generation tasks.
| Model | Evidence Recall AVG |
|---|---|
| Fast-Graph RAG | 0.87 |
| Naive RAG | 0.79 |
| Raptor | 0.90 |
| Light-RAG | 0.89 |
| Hippo RAG2 | 0.90 |
| Path RAG | 0.92 |
| Graph RAG | 0.90 |
| WGS RAG | 0.98 |
| Model | Fact Retrieval | Complex Reasoning | Contextual Summarize | Creative Generation | AVG |
|---|---|---|---|---|---|
| Fast-Graph RAG | 0.84 | 0.88 | 0.88 | 0.89 | 0.87 |
| Naive RAG | 0.79 | 0.78 | 0.73 | 0.85 | 0.79 |
| Raptor | 0.92 | 0.89 | 0.93 | 0.84 | 0.90 |
| Light-RAG | 0.90 | 0.89 | 0.96 | 0.80 | 0.89 |
| Hippo RAG2 | 0.89 | 0.94 | 0.92 | 0.83 | 0.90 |
| Path RAG | 0.94 | 0.90 | 0.92 | 0.91 | 0.92 |
| Graph RAG | 0.90 | 0.89 | 0.90 | 0.92 | 0.90 |
| WGS RAG | 0.99 | 0.99 | 0.99 | 0.95 | 0.98 |
Gen Accuracy is largely model-dependent; Evidence Recall better reflects system performance.
Overall Rank
#1
(Avg score: 88)
Compared to HippoRAG2
+12%
(+9 points)
Compared to GraphRAG
+24%
(+17 points)
Evidence Recall
0.98
Verified grounding
End-to-End Graph Reasoning
What GraphRAG Benchmark Measures
GraphRAG-Benchmark evaluates the full GraphRAG pipeline:
Graph Construction: extracting entities/relations and building useful structure
Knowledge Retrieval: selecting correct nodes/paths for multi-hop questions
Generation & Reasoning: connecting evidence into a logically consistent explanation and answer
It also scores evidence relevance and reasoning consistency, reflecting enterprise requirements where “why this answer” matters as much as the answer itself.
Graph-based RAG validation
Why We Ran This
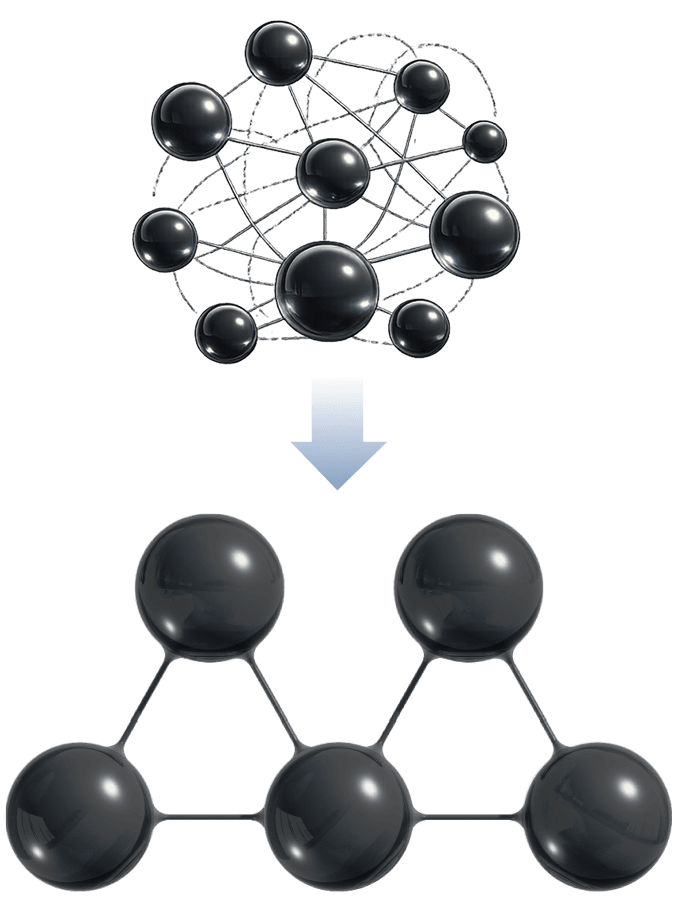
Our goal is to prove that processing data through the Wisdom Graph structure strengthens end-to-end RAG performance. By applying our reasoning, the graph can create new nodes, merge or remove duplicates, and refine relationships—resulting in a more coherent, higher-signal knowledge structure for retrieval and grounded answering.
We tested WGS RAG to measure how consistently these graph-level improvements translate into better graph-based retrieval and evidence-grounded, multi-hop reasoning, beyond prompt-only tuning. Strong results in this setting increase confidence that the same approach can transfer to other complex, evidence-heavy domains that demand reliability and auditability.
What This Result Shows
These results highlight that performance improvements come from more than retrieval alone.
A graph-aware layer that improves path selection and evidence-grounded reasoning can materially raise quality in complex, multi-hop medical queries.
“WGS RAG improves medical-domain GraphRAG quality by raising evidence recall and reasoning consistency—not just answer fluency.”
Why It Matters in Production
High-stakes domains (medicine, healthcare, law, finance) require systems that are not only accurate, but also grounded, reproducible, and explainable.
Medical-domain GraphRAG results provide evidence that WGS RAG can improve trust and reliability where incorrect or ungrounded outputs are unacceptable.
More Benchmark Results
Interested in our Wisdom Graph System beyond this benchmark?
Get a demo, see the benchmarks, or integrate today.
Contact Us